Document AI
Color-Coded Schedule PDFs to Reviewable Excel Rows
A Python document extractor converts calendar grids and highlight colors into structured scheduling-preference rows.
The problem
Scheduling information arrived in dense PDF calendars. Dates and shifts were positioned in a grid, while highlight colors carried availability and preference information. Copying text alone lost that meaning, and some staff calendars continued across multiple pages.
What I built
Native-PDF text and drawing extraction with dynamic calendar-grid detection.
Classification of schedule pages so legend pages are not treated as rosters.
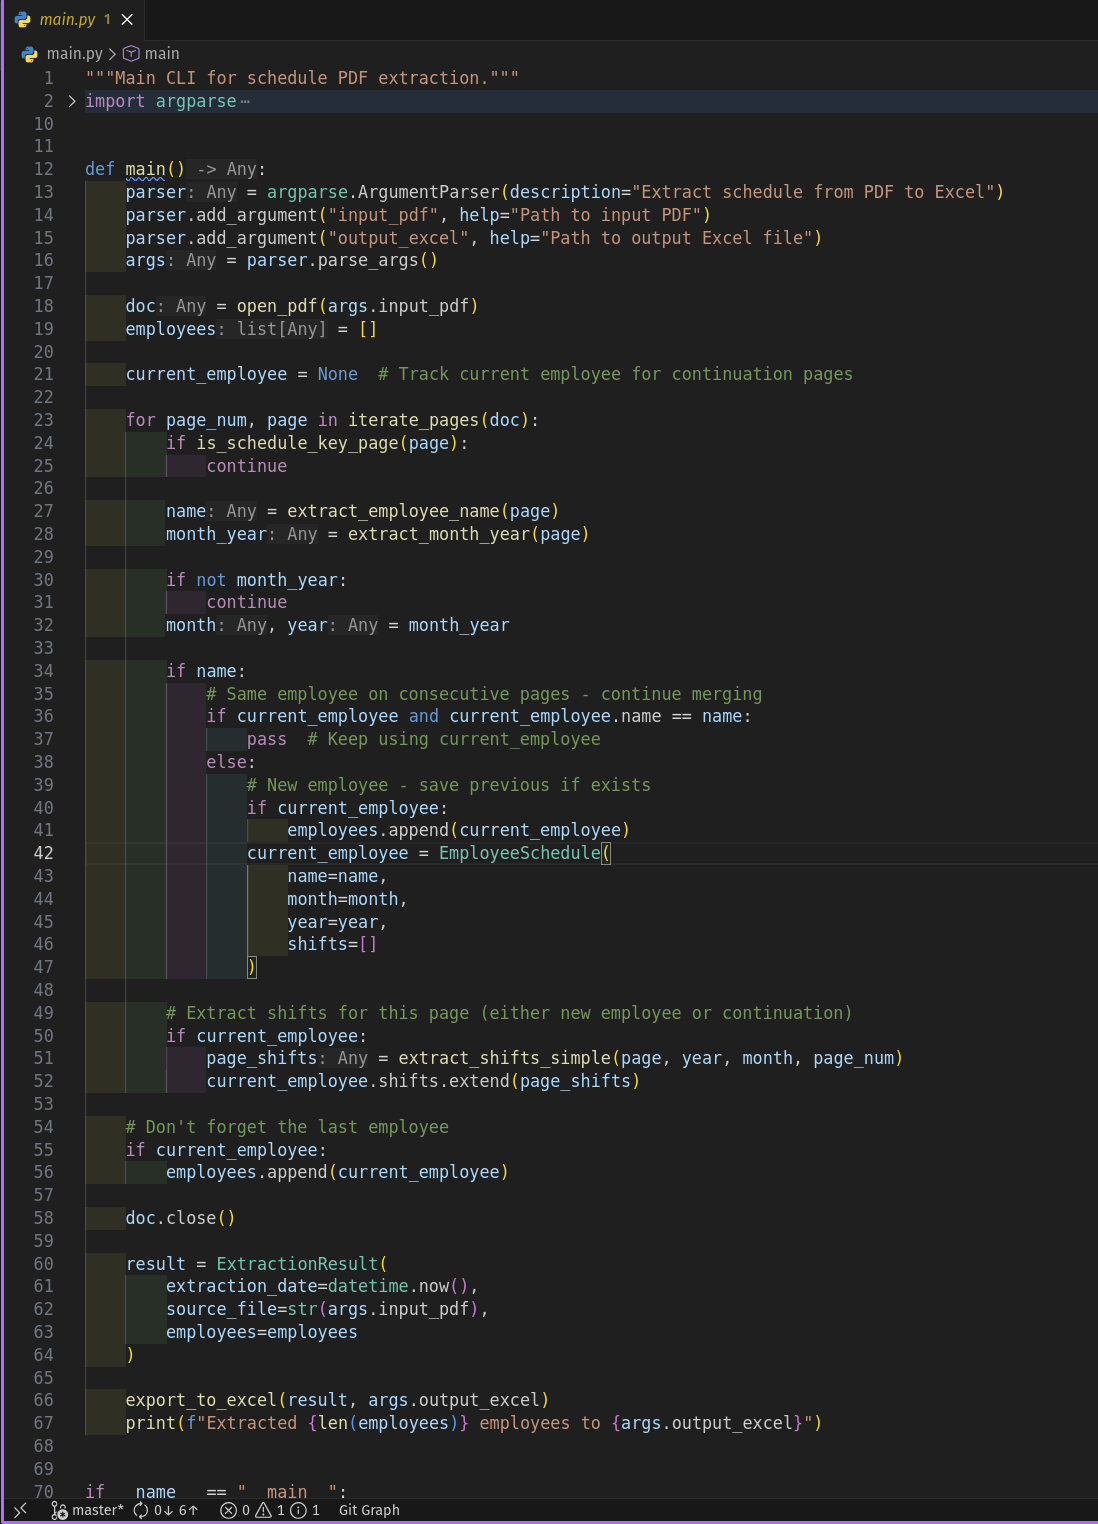
Extraction of dates, shift labels and color-coded preference values.
Continuation-page handling and duplicate-row removal.
Excel export with a readable legend for the request codes.
Tests around grid detection, color mapping and header parsing.
The deterministic native-PDF path is distinct from the related vision inspection prototype; the two are not presented as separate delivered client projects.
The outcome
The extractor produces rows a scheduling coordinator can compare with the source calendar. Unknown colors and unreadable cells are not guessed. This is operational document processing, not a clinical decision system. No measured accuracy figure is claimed.
Working on something similar?
Discuss a similar project →