Data Extraction
Resumable Python Listing Extraction to CSV
A Python listing extractor saves results incrementally to CSV and JSON Lines, then uses completed listing IDs to resume interrupted batches.
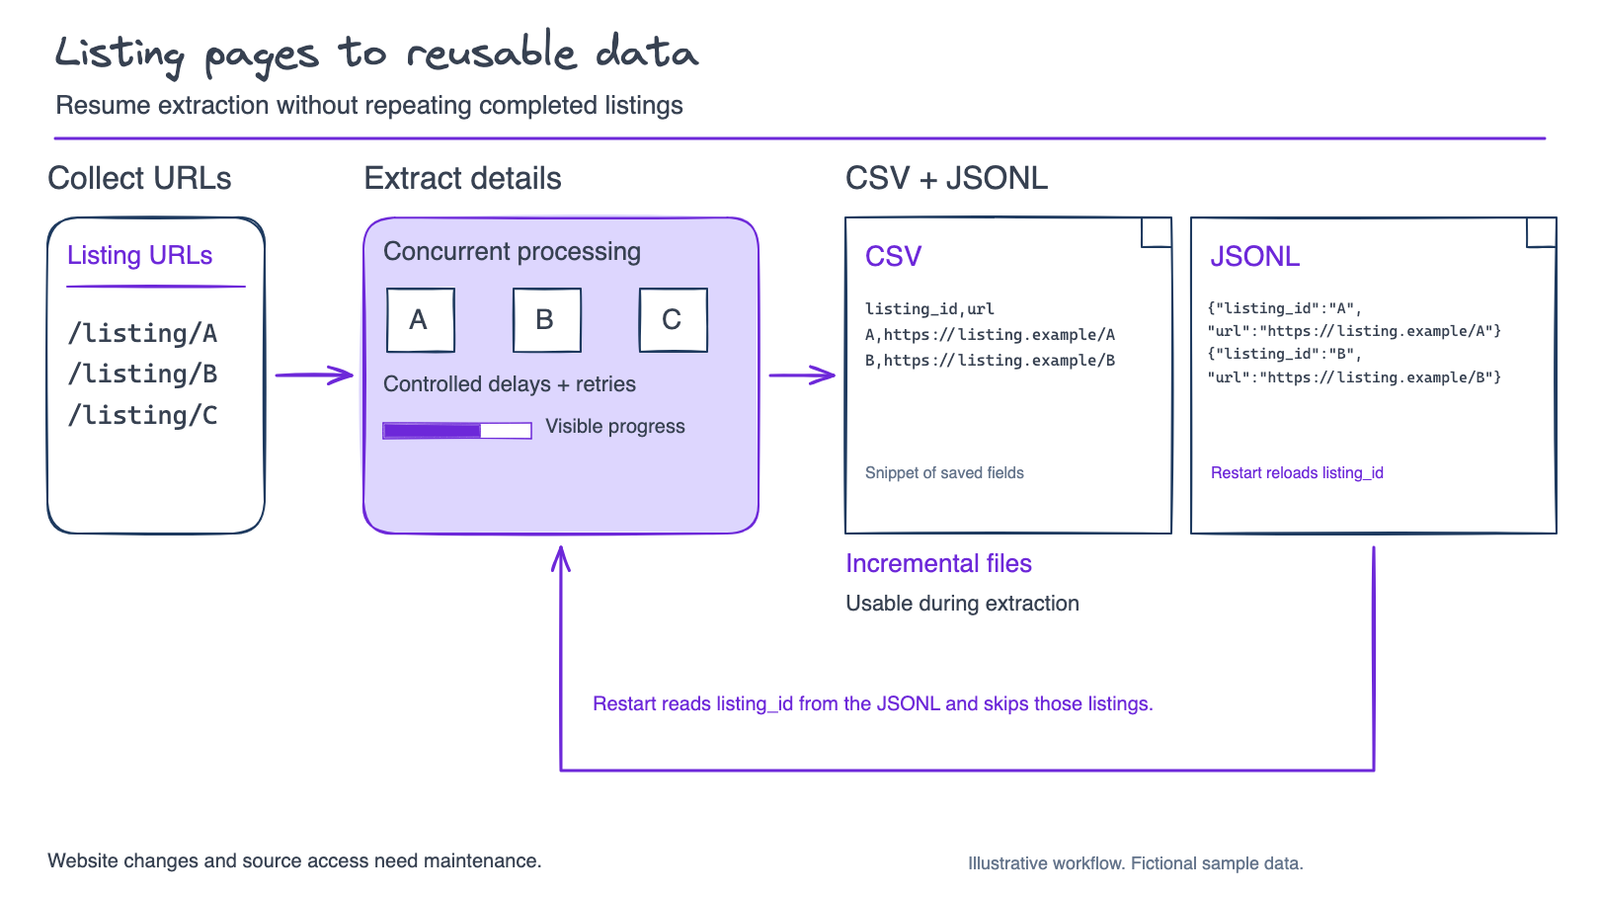
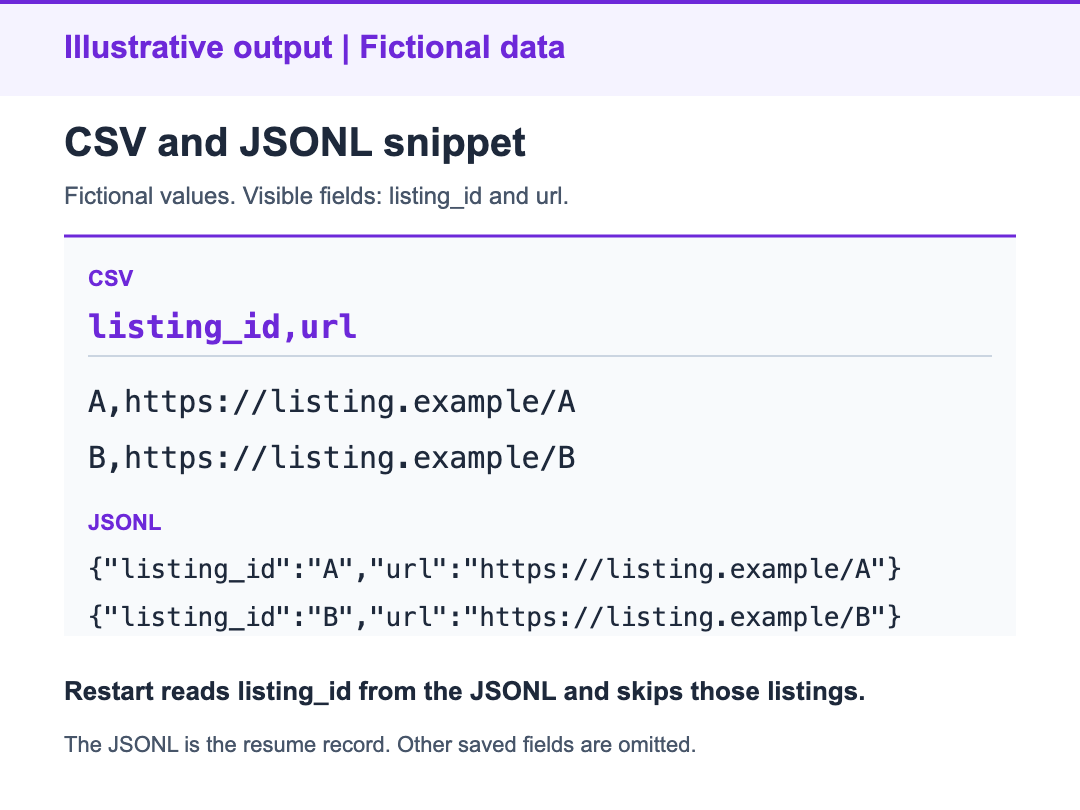
Illustrative listing extraction with incremental CSV and JSON Lines output. Restart reads completed listing IDs from saved JSON Lines records; processing settings are defined in code.
The problem
The client needed structured data from many listing pages. Restarting an interrupted batch should not mean repeating every completed listing, and reviewers needed usable output before the final page had finished.
What I built
Separate stages for collecting listing URLs and extracting their details.
Concurrent workers with request delays and retry handling.
Incremental CSV and JSON Lines output as records complete.
Resume logic that reads listing IDs already saved in the JSON Lines file and skips them on a later run.
Progress reporting and optional environment-based proxy settings.
Inputs and handoff
The extractor starts from source listing pages and saves detail records to files for review. Worker count, delays and retry limits are set in the scraper code; they are not user-facing runtime controls. The saved JSON Lines records provide the completed-ID store rather than a separate checkpoint file.
The outcome
The result is a batch-extraction process with visible progress and output that can be reused across interrupted runs. Incremental files let reviewers inspect completed records while the batch continues. Changes to page layouts and source access still need maintenance and validation.
Who this helps
Teams collecting listing data through a defined, authorized process. A Data Extraction Automation Sprint can scope the fields, source access and export handoff.
For a similar project, share a sample listing URL, the fields you need and your preferred output format.
Related work
- Browser Search Automation from a Spreadsheet
A spreadsheet-driven browser workflow returns search result URLs, timestamps and row status so operators can review each search run.
Working on something similar?
Discuss a similar project